One viral post is not the same claim as a strong campaign
A case study opens with one big number for the whole campaign, and further down there is a screenshot of the post that took off. The layout rarely tells you which of the two is carrying the result. If most of the headline figure came from a single post, you are not looking at a campaign. You are looking at a post.
The headline number and the post that made it
Campaign results are almost always reported in aggregate: total reach, average engagement per post, follower growth over the period. Each summarises a distribution you cannot see. An average moves toward whatever extreme value you add to it, so one post performing at many multiples of an account’s usual range can lift a per-post average nothing else came close to.
This is an observation about the number, not an accusation about the people. An aggregate cannot distinguish between forty posts that each worked and thirty nine that were fine plus one that was extraordinary. Both produce the same headline, and only one supports what a reader concludes from it, that this agency can make an account perform. Asking what a summary conceals is the habit behind how to read a marketing case study.
What a single-post case study is actually a claim about
A viral post is real evidence. It proves that this creative, at this moment, to this audience, reached a lot of people. That is a claim about an artifact. A campaign result is a claim about a process: the approach produced outcomes across a run of work, implying the agency could do it again elsewhere. One is skill in a moment, the other is repeatable skill, and the second is what a reader is usually assessing.
The gap matters because reach at the top end has drivers no agency controls: platform distribution, timing, the mood of the audience that week. Good work makes an outsized outcome more likely, but it is not fully attributable to method, so a repeatability claim needs evidence beyond the one instance. Same family as mistaking a seasonal tailwind for a campaign effect.
A hypothetical worked example
Every figure below is invented for illustration. It does not describe any real case study, account, or agency’s reported result.
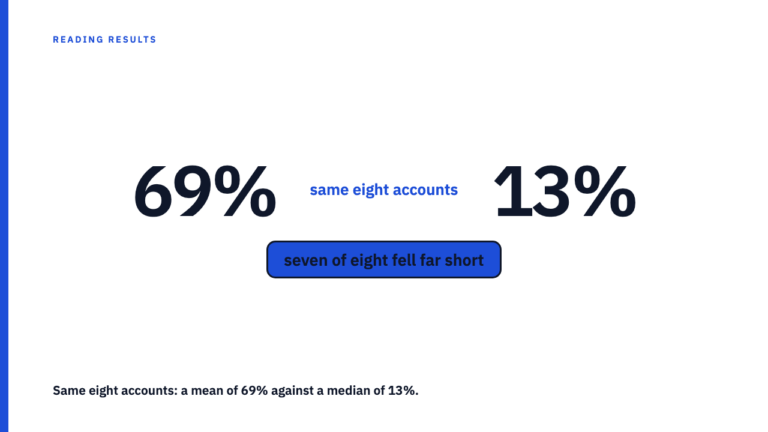
Picture a hypothetical campaign of forty posts on an account whose posts normally land near five hundred engagements. Thirty nine behave as usual and total 19,500 engagements between them. The fortieth catches distribution and takes 60,000 on its own. The campaign total is 79,500, so the average across forty posts is 1,987.5, and the write up can accurately say it averaged just under two thousand per post.
Now take the outlier out. The remaining thirty nine average 500 each, and the median post across all forty is also about 500, because the median asks which post sits in the middle, not what the pile adds up to. So the same hypothetical campaign supports two honest sentences: it averaged nearly 2,000 engagements per post, and its typical post got 500.
Four questions that separate the two claims
- Does it report per post, or only in total? A total or average with no per-post breakdown and no range cannot answer the question. That is missing evidence, not bad evidence.
- If a standout post is named or screenshotted, is the rest of the campaign shown too? The useful version also shows what the other posts did, or gives a figure with the standout excluded.
- Is the window short enough that one post could plausibly account for most of the volume? A short window with few posts gives one piece of content more room to carry the total.
- Does the framing claim repeatability, or stay scoped? Compare “this post reached this many people” with “this is how we grow every account we run”. The second needs more than one post underneath it.
What a sustained-performance case study looks like instead
A case study supporting a process claim shows performance holding or climbing across multiple posts or reporting periods, with the good posts forming a band rather than a single spike.
A standout post inside that picture is not a problem. Strong campaigns produce outliers. The test is whether the campaign still reads as a good campaign once you set that post aside, not whether an outlier exists at all. When one number looks far better than everything around it, asking what the rest are doing is the move in why the best metric on a dashboard is rarely the real story.
Why this distinction matters when you are the one reading the pitch
Credit one viral post as proof of a repeatable process and you have set an expectation the next campaign may not meet, one the evidence never actually made. A separate filter sits above all of this, namely which case studies get published at all. The job here is smaller: look at the number in front of you, and work out how many posts it took.
Read more results, or add yours
Browse the case study library and check whether the numbers are shown per post or only in aggregate. If you have published work with results attached, you can submit your own and keep the credit with it.
FAQ
If a case study shows one incredible post, does that mean the rest of the campaign was weak?
No. Strong campaigns contain standout posts too. The test is whether the case study shows the campaign holding up with that post excluded. Without that, you have missing evidence rather than proof of weakness, and the honest answer is that you cannot tell yet.
Is it dishonest for an agency to publish a case study built around one viral post?
Usually it is a scoping problem rather than a dishonesty problem. Saying that a post reached a certain number of people is accurate, and publishing it is fair. The claim goes wrong when the framing widens, when one result is presented as how the account grows every month. Judge the scope of the sentence rather than the motive behind it.
How many posts does a campaign need before a result counts as sustained rather than a spike?
There is no fixed threshold, and inventing one would be the kind of unsourced number this site helps readers catch. Look instead for whether the case study shows a trend across several posts or reporting periods rather than a single peak. A pattern is what makes a result read as sustained, whatever the count.